NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with 3B Active Parameters, and NeMo Switchyard Model Router
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.
246 stories · all sources
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.
Object removal models have improved faster than the metrics used to judge them. Diffusion erasers now reconstruct shadows, reflections and occluded structure convincingly, yet PSNR, SSIM, LPIPS, ReMOVE and CFD frequently rank their outputs the wrong way. The root cause…
LTX-2.5 brings frontier video generation to local NVIDIA hardware: 6.8-second clips, native multishot, day-one ComfyUI, open weights.
In this tutorial, we build a complete quantitative backtesting workflow with OctoBot and OctoBot-Script while keeping the environment isolated from Colab’s preinstalled dependencies. We configure a rule-based trading strategy that combines RSI-based oversold signals, EMA trend confirmation, and ATR-driven adaptive…
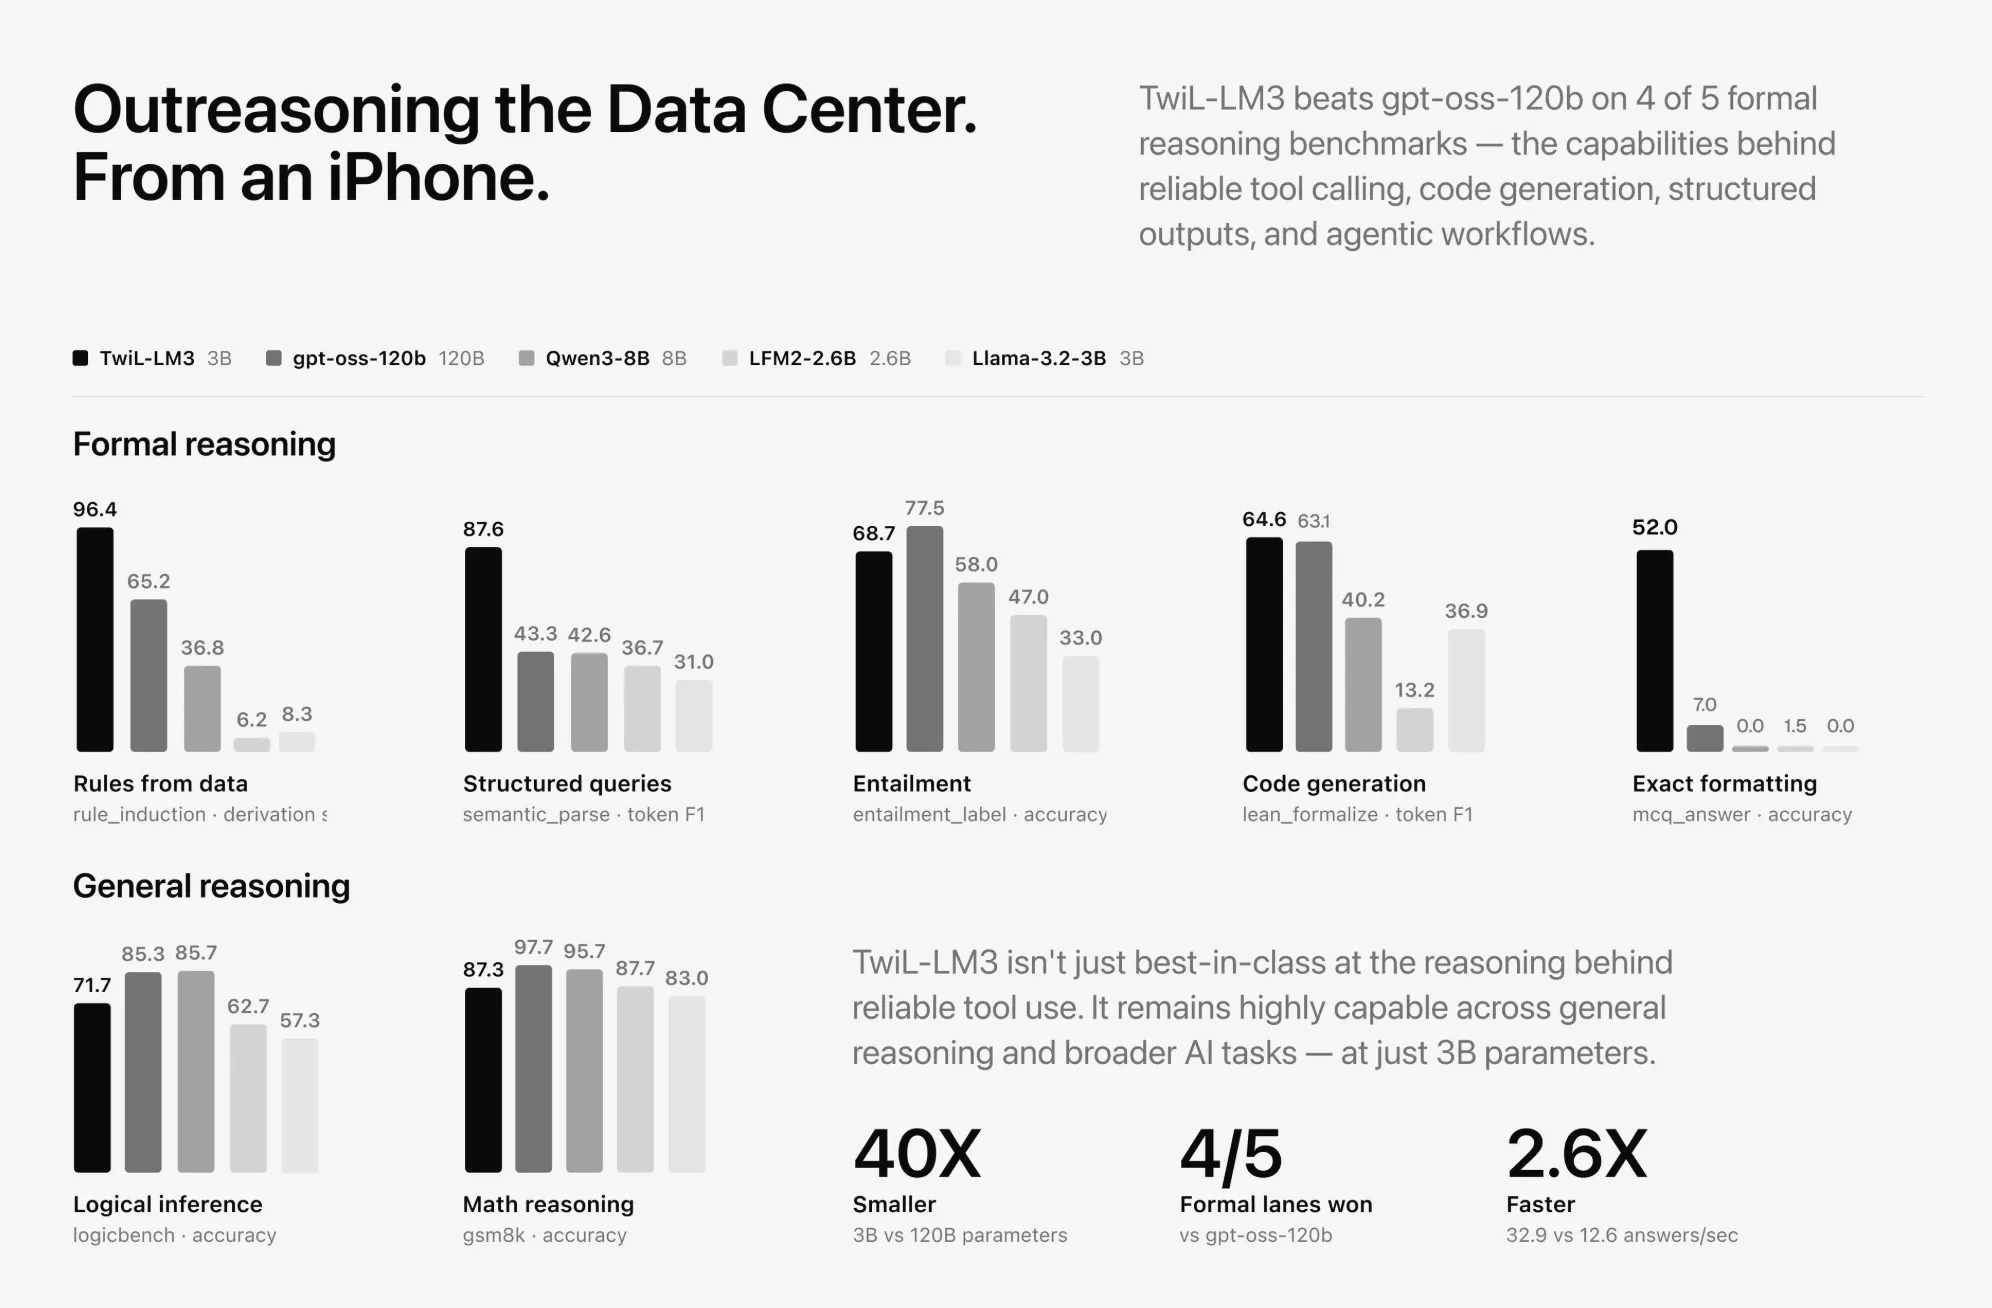
webAI has released TwIL-LM, a family of formal-logic models at 1.7B and 3B parameters that translate English into first-order logic and check whether conclusions follow from premises. The 3B runs on CPU or 4GB of VRAM; the 1.7B downloads at…
In this comprehensive guide, we demonstrate how to implement a complete, programmable MiniMax-H3 multimodal generation pipeline. By leveraging ComfyUI as a headless backend, we walk through setting up an automated inference environment that handles hardware profiling, model weight downloading, dynamic…
Meta's Muse Glimmer is a 30B open-weights agentic model under Apache 2.0. It fits 24 GB VRAM and decodes 3.1x faster with DFlash speculation.
ByteDance’s Seed team has introduced SeedRealtime, a native audio-visual full-duplex LLM. The model fuses audio, video and text in a single unified architecture. It interacts in real time over continuous multimodal streams, rather than one turn at a time. Seed…
NVIDIA releases NemotronLabs VoiceChat 11B, an open full-duplex speech-to-speech model with 448 ms latency and live tool calling.
A verified 2026 comparison of LLM observability platforms covering tracing depth, evaluation capability, production monitoring, and pricing.
This tutorial provides a comprehensive guide to building a robust sentiment analysis workflow. By combining classical TF-IDF baselines with modern parameter-efficient fine-tuning (DistilBERT + LoRA), we explore deep model interpretability, calibration, and semi-supervised techniques to achieve scalable sentiment inference
Long agent runs accumulate state that no transcript records — edited files, a live dev server, installed packages, a warm prompt cache. When an agent misreads a traceback at step 10 and rewrites a correct file, patching forward burns tokens…